Web Unlocker API Tutorial: Python and Node.js, Blocked vs Unblocked
Working Python and Node.js code for a web unlocker API: the same request against a site that blocks plain clients and one that does not, how to read what the unlocker reports, and a helper that only pays for the unlocker when a block is detected.
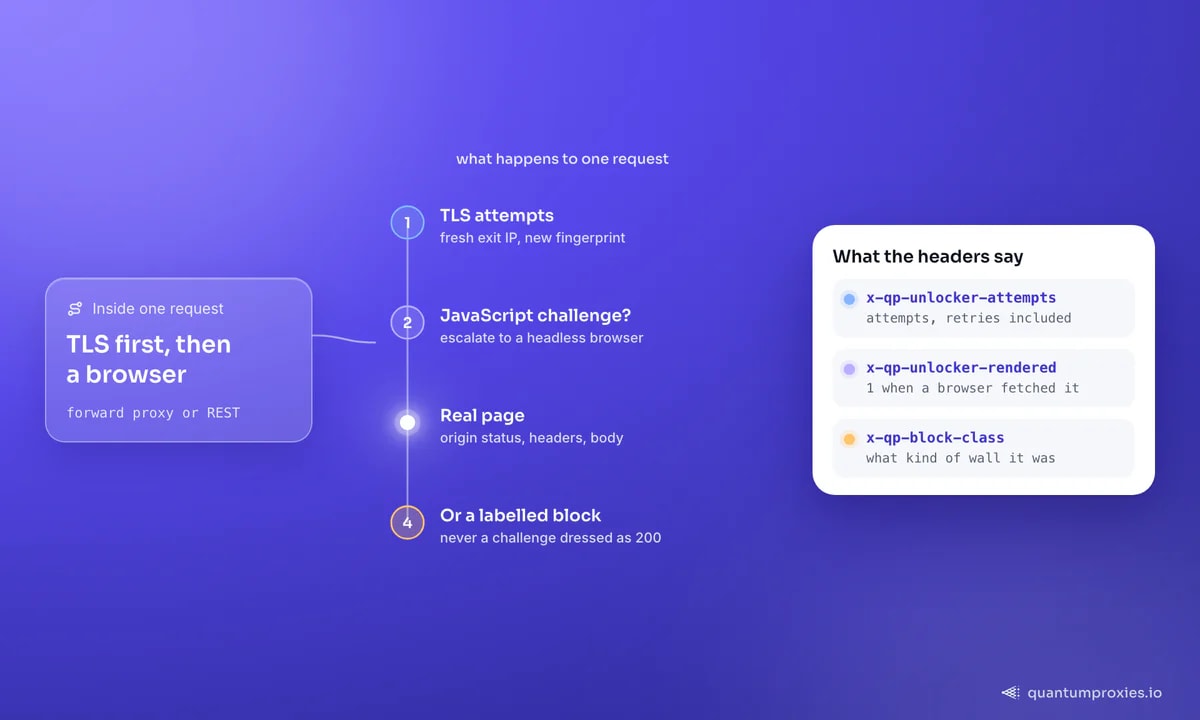
A web unlocker API replays an HTTP request from a residential IP under a browser TLS fingerprint, retrying on a fresh IP and switching to a real browser when the site answers with a challenge. This web unlocker API tutorial shows it in Python and Node.js, on a site that blocks plain clients and one that does not.
Every result quoted below was measured on 29 September 2026: the same URL fetched with plain curl from a datacenter server in Frankfurt, with plain curl through a residential proxy with a US exit, and through the QuantumProxies.io Web Unlocker with a US exit. Where a site did not need the unlocker, we say so, because the cheapest request is the one that works without it.
- Two ways in: a forward proxy at
unlock.quantumproxies.io:9000for code that already speaks proxy protocol, orPOST /api/v1/scraper/unlockwith your API key for everything else. - What you get back: the origin's status, headers and body, plus
x-qp-*headers saying how many attempts it took, whether a browser ran, and what kind of wall stopped it if one did. - When you do not need it: Wikipedia, GitHub, docs.python.org, Hacker News and books.toscrape.com all answered plain requests in our test. Try plain first and escalate only on a detected block.
What you need before you start
- A QuantumProxies.io account with Web Unlocker bandwidth. The unlocker bills from a prepaid GB balance, separate for the residential tier and the mobile tier (4G/5G carrier exits).
- For the forward proxy: a proxy sub-user created on the Web Unlocker page of the dashboard. It looks like
unlock-XXXXXXXXwith its own password. It is not your API key. - For the REST endpoint: an API key from the dashboard, sent as
Authorization: Bearer. - Python 3.10 or newer with
requests, and for the Node.js part Node 18 or newer with theundicipackage.
Keep both secrets in environment variables. The examples read QP_UNLOCK_USER, QP_UNLOCK_PASSWORD and QP_API_KEY. If the proxy password contains characters such as @ or :, URL-encode it with urllib.parse.quote before you put it in a proxy URL.
Step 1: see the block with plain Python requests
Start with the failure, so you know what you are fixing. The target is an Indeed job search. From our Frankfurt datacenter server it answered 403 with a page titled 'Security Check - Indeed.com'. Through a plain residential proxy it still answered 403, this time with a body asking the client to 'Enable JavaScript and cookies to continue'. A clean home IP was not enough.
import re
import requests

URL = "https://www.indeed.com/jobs?q=data+engineer&l=Austin%2C+TX"
HEADERS = {
    "User-Agent": (
        "Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 "
        "(KHTML, like Gecko) Chrome/150.0.0.0 Safari/537.36"
    ),
    "Accept-Language": "en-US,en;q=0.9",
}


def title_of(html: str) -> str:
    m = re.search(r"<title[^>]*>(.*?)</title>", html, re.I | re.S)
    return m.group(1).strip() if m else ""


r = requests.get(URL, headers=HEADERS, timeout=30)
print(r.status_code, "|", title_of(r.text))
# Our datacenter run on 29 Sep 2026 saw: 403 | Security Check - Indeed.com
Our measurement used curl with a Chrome User-Agent, not requests, and there is no reason to expect requests to fare better. A User-Agent string is one header. The anti-bot layer also reads the TLS handshake and the HTTP/2 settings, and those still say Python whatever User-Agent you set. That is why swapping headers rarely gets you past bot detection in Python requests; the handshake side is covered in our guide to TLS fingerprinting and why clean IPs still get blocked. A 403 means the server understood the request and refused it (RFC 9110, section 15.5.4). It does not mean your URL or your parameters are wrong.
Step 2: the same call through the forward proxy
The forward proxy is the smallest change to existing code: pass it as a proxy and nothing else moves. Targeting rides in the username. -country-us picks the exit country, -tier-mobile switches to mobile exits, and -profile-firefox (or chrome, safari, safariios, edge, brave, mobile) pins one TLS fingerprint instead of letting retries rotate it.
import os
import requests
import urllib3

urllib3.disable_warnings(urllib3.exceptions.InsecureRequestWarning)

user = os.environ["QP_UNLOCK_USER"] + "-country-us"   # e.g. unlock-XXXXXXXX-country-us
password = os.environ["QP_UNLOCK_PASSWORD"]
PROXY = f"http://{user}:{password}@unlock.quantumproxies.io:9000"

r = requests.get(
    URL,
    headers=HEADERS,
    proxies={"http": PROXY, "https": PROXY},
    verify=False,   # or verify="qp-unlocker-ca.pem", see below
    timeout=120,
)
print(r.status_code, "|", title_of(r.text))
print("attempts:", r.headers.get("x-qp-unlocker-attempts"),
      "rendered:", r.headers.get("x-qp-unlocker-rendered"))
On 29 September this returned 200 with the real results page, titled 'Now Hiring: 2,000 Data Engineer Jobs in Austin, TX | Indeed', on the first TLS attempt, in 2.6 seconds, without starting a browser.
Why verify=False? To rewrite an HTTPS request, the unlocker has to terminate your client's TLS and present its own certificate for the target host. You have two clean options. Switch verification off for this session only, as above, which is what curl -k does. Or download the unlocker CA once and trust it explicitly, so verification stays on:
curl -H "Authorization: Bearer $QP_API_KEY" \
  -o qp-unlocker-ca.pem https://app.quantumproxies.io/api/v1/scraper/unlock/ca
Then pass verify="qp-unlocker-ca.pem" instead of False. The requests advanced usage docs cover both the proxies argument and custom CA bundles. If you want neither, the REST endpoint below needs no certificate at all.
Step 3: the REST endpoint, no proxy protocol
The REST endpoint runs the same engine behind a normal HTTPS call. You describe the request you would have made (url, method, headers, body) and get the origin's answer back as JSON. The only required field is url.
import os
import requests

API_KEY = os.environ["QP_API_KEY"]

resp = requests.post(
    "https://app.quantumproxies.io/api/v1/scraper/unlock",
    headers={"Authorization": f"Bearer {API_KEY}"},
    json={
        "url": URL,
        "country": "us",
        # "tier": "mobile",        # mobile exits, billed on the mobile balance
        # "failOnBlock": True,     # HTTP 502 instead of 200 when every tier was blocked
    },
    timeout=130,
)
resp.raise_for_status()           # 402 = no unlocker GB left, 400 = bad input
data = resp.json()["payload"]

print(data["status"], "blocked:", data["blocked"])
print("attempts:", data["attempts"], "rendered:", data["rendered"],
      "escalated:", data["escalated"], "clearance:", data.get("clearance"))
if data["blocked"]:
    print("block class:", data.get("blockClass"), "vendor:", data.get("vendor"))
html = data.get("body") or ""     # text form; bodyBase64 is always present too
The response envelope is { type, message, payload }. Inside payload you get status (the origin's status code), headers, body and bodyBase64, finalUrl, the fingerprint profile, attempts, rendered, escalated, blocked and, when something stopped the request, blockClass and vendor. A usage object reports the bytes debited for the call.
One behaviour to design around: by default, a request that stayed blocked after every attempt still comes back from the API as HTTP 200, with blocked: true and the block page in body for inspection. It is labelled, not disguised. If your pipeline treats any 200 as success, set failOnBlock: true and you get a 502 carrying the same diagnostics instead. Other fields worth knowing: method and body for POSTs, render: "html" to start in a browser, waitForSelector, and returnCookies.
See how the Web Unlocker handles blocked requests
Step 4: read the x-qp headers and handle a reported block
Through the forward proxy, the unlocker reports on the response itself. These are the headers worth logging on every call:
| Header | What it tells you |
|---|---|
| x-qp-unlocker-attempts | How many attempts the request took, retries included |
| x-qp-unlocker-rendered / x-qp-unlocker-escalated | Set to 1 when a headless browser fetched the page / when the request moved up from the TLS tier |
| x-qp-unlocker-profile | Which browser fingerprint the returned attempt used |
| x-qp-clearance | What happened with the browser clearance cache on this call: minted, hit or miss |
| x-qp-session / x-qp-country | The exit session and country actually used |
| x-qp-unlocker-blocked | Present only when the page was still blocked after every attempt |
| x-qp-block-class / x-qp-vendor | What kind of wall it was, and which anti-bot vendor, when recognised |
A page that is still blocked never arrives as a silent 200. If the origin refused with its own error (403, 429, 503), that status is relayed unchanged with x-qp-unlocker-blocked set. If the origin served a challenge page with a 2xx, the proxy turns it into a 502 and puts the origin's code in x-qp-origin-status. So one check covers both:
class Blocked(Exception):
    pass


s = requests.Session()
s.proxies = {"http": PROXY, "https": PROXY}
s.verify = False  # or "qp-unlocker-ca.pem"

NEXT_STEP = {
    "js_challenge":  "a browser could not clear it; retry later in a pinned session",
    "captcha":       "interactive captcha; decide in your own code",
    "access_denied": "the site denied access; retry with a fresh session or test tier-mobile",
    "rate_limited":  "the site is rate limiting; slow down and retry later",
    "fingerprint":   "the client fingerprint was refused; retry with another profile",
    "geo":           "the content depends on location; set the country explicitly",
    "timeout":       "the target was too slow; raise x-qp-timeout or retry",
}


def unlock_get(url: str, session_id: str | None = None) -> requests.Response:
    headers = {"x-qp-session": session_id} if session_id else {}
    r = s.get(url, headers=headers, timeout=120)
    if "x-qp-unlocker-blocked" in r.headers:
        cls = r.headers.get("x-qp-block-class", "unknown")
        raise Blocked(
            f"{url}: HTTP {r.status_code}, class={cls}, "
            f"vendor={r.headers.get('x-qp-vendor')}, next: {NEXT_STEP.get(cls, 'inspect the body')}"
        )
    return r
Step 5: the Node.js version (web unlocker API in JavaScript)
In Node, fetch takes a dispatcher. Use ProxyAgent from undici for the forward proxy, and import fetch from the same package so the two versions match. The ProxyAgent documentation lists the options used here: token for the Proxy-Authorization value and requestTls for the TLS settings towards the target.
// unlock.mjs  (npm i undici)
import { readFileSync } from "node:fs";
import { fetch, ProxyAgent } from "undici";

const user = process.env.QP_UNLOCK_USER + "-country-us";
const pass = process.env.QP_UNLOCK_PASSWORD;

const dispatcher = new ProxyAgent({
  uri: "http://unlock.quantumproxies.io:9000",
  token: "Basic " + Buffer.from(user + ":" + pass).toString("base64"),
  requestTls: { rejectUnauthorized: false },
  // verified instead: requestTls: { ca: readFileSync("qp-unlocker-ca.pem") },
});

const url = "https://www.indeed.com/jobs?q=data+engineer&l=Austin%2C+TX";
const res = await fetch(url, { dispatcher, headers: { "x-qp-session": "indeed-001" } });

if (res.headers.get("x-qp-unlocker-blocked")) {
  console.error("blocked:", res.status, res.headers.get("x-qp-block-class"), res.headers.get("x-qp-vendor"));
} else {
  const html = await res.text();
  console.log(res.status, res.headers.get("x-qp-unlocker-attempts"), html.length);
}
The REST endpoint needs nothing beyond the fetch built into Node 18+:
const resp = await fetch("https://app.quantumproxies.io/api/v1/scraper/unlock", {
  method: "POST",
  headers: {
    Authorization: "Bearer " + process.env.QP_API_KEY,
    "Content-Type": "application/json",
  },
  body: JSON.stringify({ url: "https://www.indeed.com/jobs?q=data+engineer&l=Austin%2C+TX", country: "us" }),
});
const { payload } = await resp.json();
console.log(payload.status, payload.blocked, payload.blockClass ?? "-", payload.attempts);
On axios, the usual pattern for HTTPS targets behind a proxy is to pass an agent from https-proxy-agent as httpsAgent and set proxy: false, or to call the REST endpoint above and skip proxy protocol entirely.
Step 6: when you do not need the unlocker
The unlocker is billed per GB on every byte it moves, retries and browser page loads included. Sending it pages that a plain request fetches fine burns balance for nothing. In our run, these came back fine without any help:
| Site | Plain, datacenter server | Plain, residential proxy | Web Unlocker |
|---|---|---|---|
| docs.python.org (urllib.request page) | 200 | 200 | 200, 1.6 s |
| books.toscrape.com | 200 | 200 | 200, 1.9 s |
| news.ycombinator.com | 200 | 200 | 200, 4.1 s |
| en.wikipedia.org (Web scraping) | 200 | 200 | 200, 1.9 s |
| github.com (scrapy repository) | 200 | 200 | 200, 2.0 s |
| bbc.com (Technology) | 302 redirect | 302 redirect | 200, 1.4 s |
The BBC row is not a block. Our test client did not follow redirects, and the 302 is the site sending you to another URL. requests follows redirects by default and lands on the page.
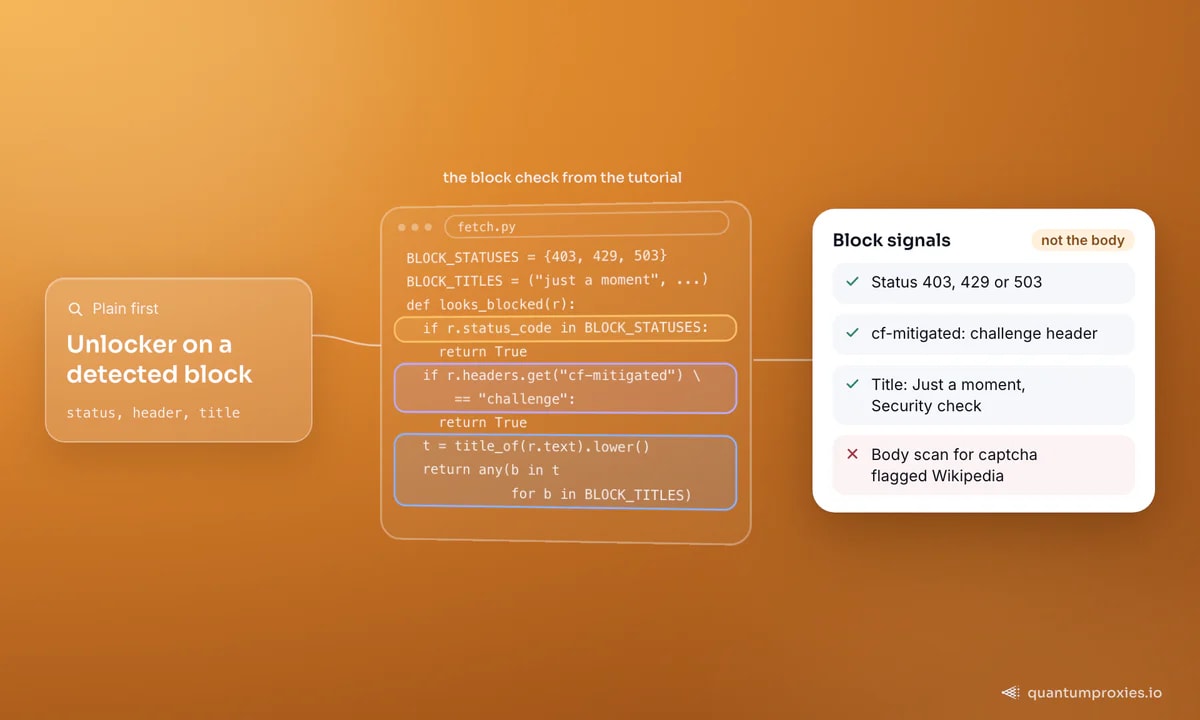
So the right pattern is plain first, unlocker on a detected block. Detection needs care. The marker scan in our own test harness flagged the Wikipedia and GitHub pages as blocked because their bodies contain the word 'captcha', even though both returned the real page with a 200. Check the status code, Cloudflare's cf-mitigated header and the page title, not the whole body:
from urllib.parse import urlsplit

BLOCK_STATUSES = {403, 429, 503}
BLOCK_TITLES = (
    "just a moment",                        # Cloudflare challenge
    "attention required",                   # Cloudflare block page
    "access denied",                        # Akamai and others
    "security check",
    "access to this page has been denied",  # PerimeterX
)
needs_unlocker: set[str] = set()            # domains that blocked plain requests


def looks_blocked(r: requests.Response) -> bool:
    if r.status_code in BLOCK_STATUSES:
        return True
    if r.headers.get("cf-mitigated") == "challenge":
        return True
    return any(t in title_of(r.text).lower() for t in BLOCK_TITLES)


def fetch(url: str, session_id: str | None = None) -> tuple[requests.Response, str]:
    host = urlsplit(url).hostname or ""
    if host not in needs_unlocker:
        try:
            r = requests.get(url, headers=HEADERS, timeout=20)
            if not looks_blocked(r):
                return r, "plain"
        except requests.RequestException:
            pass  # a reset or a timeout counts as a block too
        needs_unlocker.add(host)
    return unlock_get(url, session_id), "unlocker"   # from step 4; raises Blocked


for u in ("https://docs.python.org/3/library/urllib.request.html", URL):
    resp, route = fetch(u)
    print(route, resp.status_code, title_of(resp.text)[:60])
The except branch matters. Best Buy's laptop category never gave our plain clients an HTTP response at all: the connection failed from both the datacenter server and the residential proxy. Through the unlocker the same URL returned 200 on the first attempt in 6.3 seconds. A scraper that only checks status codes would never escalate that one.
Measured results: four sites that needed the unlocker
Measured on 29 September 2026. Plain requests were curl with a Chrome User-Agent, once from a Frankfurt datacenter server and once through a residential proxy with a US exit. Web Unlocker requests used the residential tier with a US exit. Times are wall-clock for a single request.
| Site | Plain, datacenter server | Plain, residential proxy | Web Unlocker |
|---|---|---|---|
| Indeed (job search) | 403, 'Security Check' page | 403, 'Enable JavaScript and cookies to continue' | 200, 1 attempt, 2.6 s |
| Glassdoor (company reviews) | 403, 'Security' page with captcha | 403, 'Enable JavaScript and cookies to continue' | 200, 2 attempts + browser, 17.2 s |
| Walmart (search) | 307 redirect, no results page | 307 redirect, no results page | 200, 1 attempt, 4.8 s |
| Best Buy (laptop category) | Connection failed, no response | Connection failed, no response | 200, 1 attempt, 6.3 s |
In short: Indeed, Walmart and Best Buy passed on the first TLS attempt with no browser. Glassdoor needed the full path, two TLS attempts and then a headless browser to answer the JavaScript challenge, which is why it took 17.2 seconds. For Walmart we did not record where the 307 pointed. What we can say is that neither plain client received the results page and the unlocker did.
Repeat requests to a challenge-protected site get faster when you pin a session. Send the same x-qp-session value, or keep the same -session-<id> in the proxy username, and the clearance cookie earned by the browser is reused. In a Glassdoor test on 29 September 2026, with the session pinned in the username and two separate connections, the first request took 14.0 seconds through the browser and the second 1.4 seconds, with x-qp-clearance: hit. Our guide to scraping Indeed job postings covers what to do with the page once you have it.
If you arrived here from a 403 that only happens outside the browser, our explainer on why curl gets a 403 when the browser works goes deeper into the diagnosis. For a site-by-site look at which layer you actually need, see web unlocker vs residential proxy, tested.
Frequently asked questions
Is there a free web unlocker API?
The open-source pieces are free: requests, curl_cffi for browser-like TLS, and Playwright for a real browser. Running them well is the work, because you also need clean exit IPs and a browser for JavaScript challenges. On QuantumProxies.io, creating an account is free, and unlocker traffic is billed per GB from a prepaid balance you top up in the dashboard.
Can you scrape Glassdoor or Zillow with Python?
In our 29 September 2026 test, plain requests to a Glassdoor reviews page got a 403 from both a datacenter server and a residential proxy, and the unlocker returned the page after a browser escalation. Zillow blocked the datacenter server but served the page through a plain residential proxy. Check each site's terms before you collect anything.
Can web scraping be detected?
Yes. Sites score the IP's network type and history, the TLS handshake, the HTTP/2 settings, header order and, on challenge pages, what JavaScript reports about the browser. A plain Python request fails several of those at once. That is why changing only the User-Agent rarely helps, and why the unlocker changes the IP, the fingerprint and, when needed, the whole client.
Do I need to install a certificate to use the forward proxy?
Only for HTTPS through the classic forward proxy, because the unlocker terminates TLS to rewrite the request. Either skip verification for that session (verify=False in Python, -k in curl) or download the CA from /api/v1/scraper/unlock/ca with your API key and trust it. The REST endpoint needs no certificate at all.
How do I keep the same IP across several requests?
Send the same x-qp-session header value on each request through the forward proxy, or put the same -session-<id> in the proxy username. Calls sharing that session leave from the same exit, and a clearance cookie earned by the browser is reused. On the REST endpoint, pass a sessionId with rotation set to sticky. A sticky session can last from 3 to 1,440 minutes.
The whole pattern fits in one sentence: fetch plainly, detect a block by status, header and title, send only those URLs through the unlocker, and log the x-qp headers so you know what each page cost you. Start with the residential tier, and keep the Mobile tier for targets that refuse residential ranges too.