Cloudflare "Just a Moment" in Python: Why requests Fails
Cloudflare's 'Just a moment...' page is a JavaScript challenge, and Python requests cannot run JavaScript. Here is how to detect it, why it hits servers harder than laptops, why cloudscraper-style tricks stopped being enough, and what got through in our 29 September 2026 test.
'Just a moment...' is Cloudflare's challenge page. It asks the client to run JavaScript and prove it is a browser before the site answers. Python requests cannot run JavaScript, and from a datacenter server its IP and TLS handshake already look automated. What gets through is a real browser on a clean IP, or a web unlocker that runs one.
This guide shows how to detect the challenge in Python, why the same script passes on your laptop and fails on your server, why cloudscraper-era tricks stopped being enough, and what actually got through when we tested it on 29 September 2026. That includes the site where nothing we tried got past 'Just a moment'.
- It is a challenge, not an error. Cloudflare marks challenged responses with the header
cf-mitigated: challenge. In our test they arrived as HTTP 403. - Headers will not fix it. 'Enable JavaScript and cookies to continue' means the page wants a JavaScript engine. No User-Agent string supplies one.
- Server versus laptop is mostly IP reputation plus the TLS fingerprint. A residential IP alone did not pass Indeed or Glassdoor in our test.
- What passed: the Web Unlocker got Glassdoor (after a headless browser, 17.2 s) and Indeed (first attempt, 2.6 s).
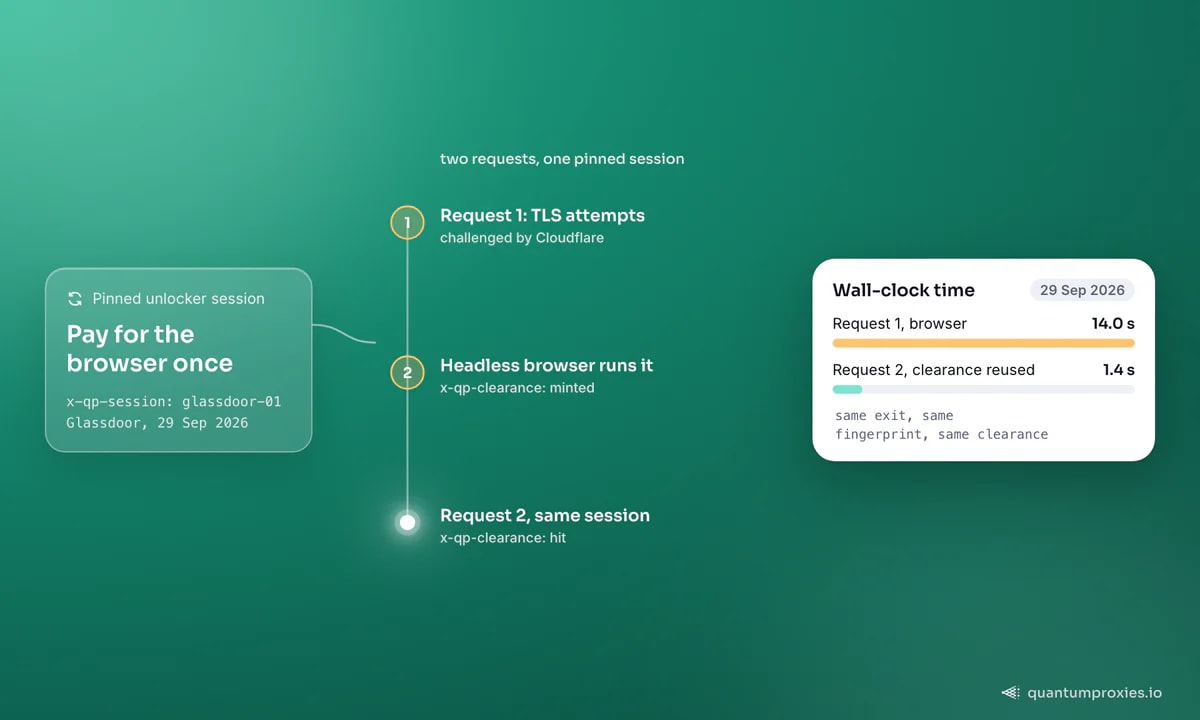
- Pin a session. Reusing the browser's clearance cut a second Glassdoor request from 14.0 s to 1.4 s in our test.
What the "Just a moment..." page actually is
Cloudflare calls it an interstitial Challenge Page: a full-page gate between the visitor and the site while Cloudflare decides whether the visitor is automated. Its documentation on challenge pages describes three kinds. A non-interactive challenge only needs the browser to run the injected JavaScript. A managed challenge lets Cloudflare pick the challenge type from the request's signals. An interactive challenge asks the visitor to do something. When the check passes, the original request continues to the site and the browser gets a cf_clearance cookie that lets it skip the gate for a while.
A Python HTTP client never gets that far. It downloads the challenge page, has no engine to run the script, and hands you the HTML of the gate instead of the page you asked for.
Why the challenge comes back as a 403, and how to detect it
In our test, every challenge page arrived with status 403, which is why raise_for_status() throws 403 Client Error: Forbidden and people search for 'cloudflare just a moment 403'. The status alone cannot tell a challenge from any other refusal, though. The reliable signal is a header: Cloudflare documents that a challenged response carries cf-mitigated: challenge, whatever resource you requested. Check that first, then the title as a fallback:
import re
import requests

URL = "https://www.glassdoor.com/Reviews/Google-Reviews-E9079.htm"
HEADERS = {
    "User-Agent": (
        "Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 "
        "(KHTML, like Gecko) Chrome/150.0.0.0 Safari/537.36"
    ),
    "Accept-Language": "en-US,en;q=0.9",
}


def title_of(html: str) -> str:
    m = re.search(r"<title[^>]*>(.*?)</title>", html, re.I | re.S)
    return m.group(1).strip() if m else ""


def is_cloudflare_challenge(r: requests.Response) -> bool:
    if r.headers.get("cf-mitigated") == "challenge":      # documented by Cloudflare
        return True
    if "just a moment" in title_of(r.text).lower():
        return True
    return "enable javascript and cookies to continue" in r.text[:20000].lower()


r = requests.get(URL, headers=HEADERS, timeout=30)
print(r.status_code, is_cloudflare_challenge(r), title_of(r.text))
# 29 Sep 2026, plain request through a residential proxy (US exit):
# 403, body asking to 'Enable JavaScript and cookies to continue'
Do not retry a challenged request in a tight loop with the same client. Each retry fetches the same gate, and some sites answer repeated failures with stricter rules. That is how scrapers end up stuck in a 'Just a moment' loop.
"Enable JavaScript and cookies to continue" and "your browser does not support JavaScript"
These strings are the fallback text of a challenge page, shown to clients that do not execute its script. When Python requests shows you one of them, the site is not complaining about your headers. It is telling you, literally, that it needs a JavaScript engine and a cookie jar that keeps what the script sets.
That is exactly what our plain residential run received from Indeed and Glassdoor: a 403 with 'Enable JavaScript and cookies to continue', from a clean home IP. Adding a Chrome User-Agent, an Accept-Language header or a Referer changes nothing, because the page is not reading them to decide. It is waiting for the script to run.
Why your scraper works locally but gets blocked by Cloudflare on a server
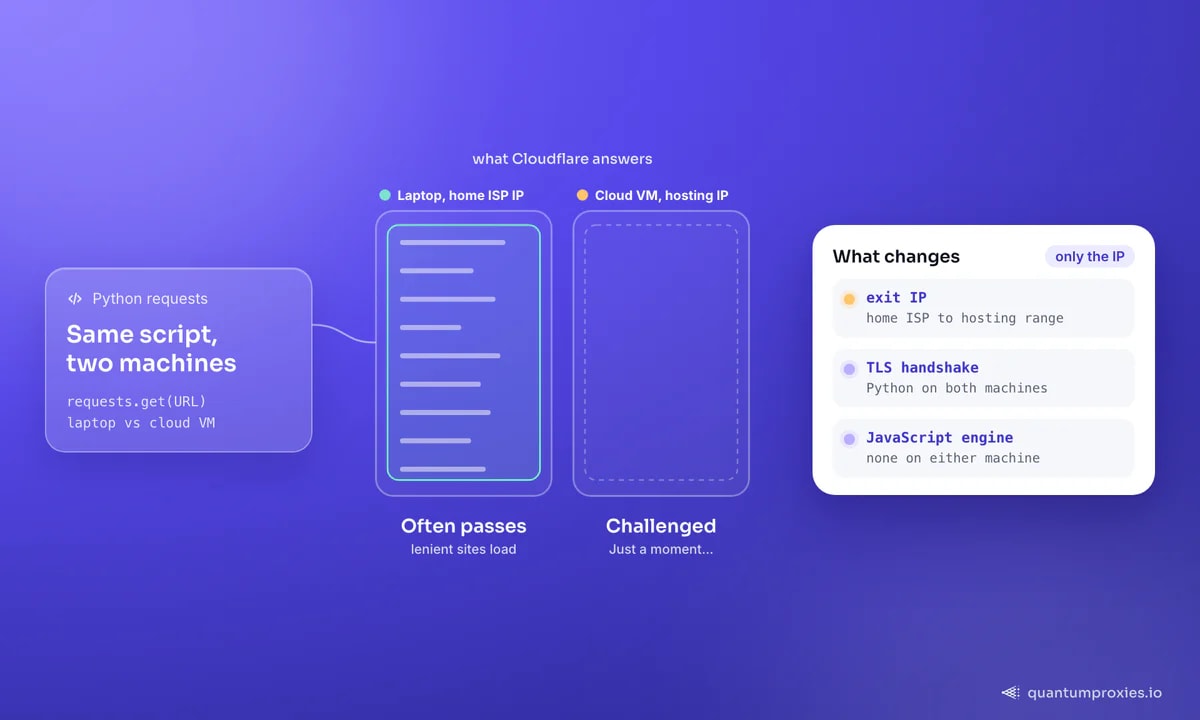
This is the most common version of the complaint: the script works on a laptop, then gets 'Just a moment' as soon as it runs on a cloud VM. Two things change between those machines.
- The IP. On your laptop the script leaves from a home ISP address. On a VM it leaves from a hosting provider's range, which bot defences score as likely automated before they read anything else. Our Frankfurt datacenter server was refused by Glassdoor, Indeed, Zillow and Leboncoin, among others.
- The TLS fingerprint. Python's handshake looks like Python on both machines, but on a home IP a site may tolerate it and on a hosting IP it rarely will. Our explainer on curl_cffi vs requests shows how much of the handshake a library controls.
The residential column of our test shows the limit of fixing only the IP. Zillow and Leboncoin served the real page to a plain request through a residential proxy. Indeed and Glassdoor still answered with the JavaScript challenge. Your laptop can hit the same wall on a stricter site. It simply hits it less often.
Why cloudscraper-era tricks stop working
cloudscraper was built for Cloudflare's older 'I'm Under Attack' page. That page mostly checked whether the client could run a JavaScript computation, so the library fetched the challenge, solved the script in an embedded interpreter, sent the answer back and kept the cookie, all on top of requests. For a long time that was enough, and it is the reason 'cloudscraper alternative' is now a search people make.
Several things have moved since then, and they do not depend on any one library version:
- The handshake still says Python. A library built on requests connects through Python's TLS stack, so the ClientHello does not match the browser its User-Agent claims to be. That mismatch is visible before any JavaScript runs.
- The challenge is not just arithmetic any more. Managed challenges pick the check from the request's signals, and Cloudflare's JavaScript detections read the browser environment. An interpreter that evaluates a script is not a browser that renders a page.
- Clearance is bound to the client. Cloudflare's clearance documentation says a cf_clearance cookie is tied to the visitor and device it was issued to, to prevent reuse across machines. Copying one from your browser into a script on another machine is designed to fail.
- The IP is still yours. Solving the page does not change a hosting-range IP, and some sites refuse those before any challenge is served.
As of 29 September 2026, the cloudscraper repository's last push was in June 2025. That is not a verdict on any particular site, and we did not benchmark it for this article. It does mean you should test it against your own targets rather than assume it works. The alternatives each fix part of the problem. curl_cffi reproduces a browser TLS handshake but runs no JavaScript. Playwright or another real browser runs the challenge but still needs a clean IP, and is heavy to operate at volume. The unlocker combines the two and tells you when neither worked.
What gets through: the web unlocker path
The QuantumProxies.io Web Unlocker handles a GET in stages. First, up to three TLS attempts, each on a fresh residential exit under a different browser fingerprint. If every attempt comes back challenged, it escalates to a headless browser that runs the challenge. If the page is still blocked after that, you get an error status with x-qp-unlocker-blocked and a block class, never a challenge page dressed up as a 200. From Python it is a proxy setting:
import os
import time
import requests
import urllib3

urllib3.disable_warnings(urllib3.exceptions.InsecureRequestWarning)

user = os.environ["QP_UNLOCK_USER"] + "-country-us"          # unlock-XXXXXXXX-country-us
PROXY = f"http://{user}:{os.environ['QP_UNLOCK_PASSWORD']}@unlock.quantumproxies.io:9000"

s = requests.Session()
s.proxies = {"http": PROXY, "https": PROXY}
s.verify = False                     # or the unlocker CA file from /api/v1/scraper/unlock/ca
s.headers["x-qp-session"] = "glassdoor-01"   # same value on every call: same exit, reusable clearance

for attempt in (1, 2):               # same page twice here; in practice, the next page
    t0 = time.monotonic()
    r = s.get(URL, timeout=120)
    print(attempt, r.status_code, f"{time.monotonic() - t0:.1f}s",
          "rendered:", r.headers.get("x-qp-unlocker-rendered"),
          "clearance:", r.headers.get("x-qp-clearance"),
          "block:", r.headers.get("x-qp-block-class"))
The x-qp-* headers are read by the unlocker and never forwarded to the site. If you would rather not deal with the certificate at all, the REST endpoint POST https://app.quantumproxies.io/api/v1/scraper/unlock takes the URL in a JSON body with your API key and returns blocked, blockClass and vendor in the response. Our web unlocker API tutorial walks through both.
Measured: two Cloudflare-style walls that passed
Measured on 29 September 2026. Plain requests were curl with a Chrome User-Agent, from a Frankfurt datacenter server and through a residential proxy with a US exit. The unlocker used the residential tier with a US exit. Times are wall-clock for one request.
| Site | Plain, datacenter server | Plain, residential proxy | Web Unlocker |
|---|---|---|---|
| Glassdoor (company reviews) | 403, 'Security' page | 403, 'Enable JavaScript and cookies to continue' | 200, 2 attempts + headless browser, 17.2 s |
| Indeed (job search) | 403, 'Security Check' page | 403, 'Enable JavaScript and cookies to continue' | 200, 1 attempt, no browser, 2.6 s |
Glassdoor is the full path. Two TLS attempts were challenged, then the headless browser ran the challenge and returned the reviews page. Indeed is the interesting one: the challenge that the plain residential request received never appeared for the unlocker's first attempt. A browser TLS fingerprint on a fresh residential exit was enough, without a browser.
Get past JavaScript challenges with the Web Unlocker
Reusing the clearance: why the second request is fast
The browser escalation is the slow part, and you do not want to pay for it on every page. When the headless browser passes a challenge, it earns a clearance. Send the same x-qp-session value, or keep the same -session-<id> in the proxy username, on the following requests and they leave from the same exit, reusing that clearance instead of running the browser again. The x-qp-clearance header tells you what happened on each call: minted when a new clearance was earned, hit when a stored one was reused, miss when there was nothing to reuse.
In a Glassdoor test on 29 September 2026, with the session pinned in the proxy username and two separate connections, the first request went through the browser in 14.0 seconds (minted) and the second came back in 1.4 seconds (hit). The pinning matters because of how Cloudflare binds clearance: it is tied to the visitor and device that earned it, and it stays valid for the duration the site configures unless Cloudflare decides the session looks suspicious. Change the exit or the fingerprint and you are a new visitor again.
When plain requests is still fine on a Cloudflare site
Plenty of sites run behind Cloudflare only as a CDN, or with bot rules that let ordinary traffic through, and plain requests works on them. Being 'on Cloudflare' is not a reason to reach for a browser. The signal is the response. If there is no cf-mitigated: challenge header, no 'Just a moment' title and no 403, keep the plain request, and escalate only the URLs that actually get challenged. The plain-first helper in our tutorial does exactly that.
Two neighbouring problems have their own guides. A page that says 'Error 1020 Access denied' is a firewall rule refusing you, not a challenge, and no amount of JavaScript fixes it; see what triggers Cloudflare error 1020 and what fixes it. For the wider picture of Cloudflare's defences beyond Python, read how to bypass Cloudflare challenges in 2026. If the page behind the wall is Glassdoor, our guide to scraping Glassdoor salaries and reviews covers the data side.
Frequently asked questions
Why does my scraper work locally but get blocked by Cloudflare in the cloud?
Because the IP changes. At home your script leaves from a residential ISP address; on a cloud VM it leaves from a hosting range that bot defences distrust on sight. The Python TLS handshake is the same on both, and on a stricter site it gets challenged even from home. In our test, a residential IP alone did not pass Indeed or Glassdoor.
Why does Cloudflare's "Just a moment" page return a 403?
The challenge page is served instead of the page you asked for, and in our test it came with status 403, so requests raises '403 Client Error: Forbidden'. The status is not specific to challenges. Check the cf-mitigated response header, which Cloudflare documents as set to challenge on every Challenge Page response, or the 'Just a moment' title.
Is cloudscraper still working, and what is a good alternative?
It may still work on sites with lenient settings, so test it against your targets. It runs on Python's TLS stack and solves scripts in an interpreter, while current challenges also look at the handshake and the browser environment. Alternatives: curl_cffi for a browser handshake, a real browser for the JavaScript, or a web unlocker that does both.
Can Python requests pass a Cloudflare challenge on its own?
No. requests does not execute JavaScript, so it cannot complete a challenge that depends on running the page's script. It can fetch pages from Cloudflare sites that are not challenging you. Once cf-mitigated: challenge appears, you need a real browser, directly or through a service that runs one, and ideally a clean residential IP.
How long does a Cloudflare clearance last?
As long as the site configures it to. Cloudflare calls the setting Challenge Passage, and clearance can end early if Cloudflare decides the session looks suspicious. The cf_clearance cookie is tied to the visitor and device that earned it, so it only helps if later requests keep the same exit and fingerprint, which is what pinning x-qp-session does.
The short version: 'Just a moment...' asks for a browser, so no header trick in requests will satisfy it. Detect it with cf-mitigated, keep plain requests for everything that is not challenged, send the challenged URLs through something that runs a real browser from a clean IP, and pin a session so you pay for that browser once rather than on every page.